Table of Contents
Key Takeaways
- GEO optimizes for AI citations in generated answers by using clean semantic HTML and JSON-LD schema that LLMs can parse correctly.
- Use server-side rendering or static generation because AI crawlers skip JavaScript-heavy pages.
- Track citation frequency as your primary metric: 8-15% is good, 15-25% is market leader territory.
- Keep entity references consistent with the same @id URLs so AI models build a unified knowledge graph.
- Validate JSON-LD schema on every deployment since broken markup is worse than no markup.
- Use Serpstack and Zenserp APIs to track competitor citations and reverse-engineer their content strategies.
We are now firmly in the “Zero-Click” era of 2026. The traditional organic traffic funnel is shrinking as users increasingly receive direct answers from AI Overviews, ChatGPT, and Perplexity. For developers and technical content creators, this creates a critical blind spot: traditional SEO tools track rankings, but they fail to explain why an LLM chose to cite Competitor A over Competitor B.
This introduces Generative Engine Optimization (GEO). Unlike traditional SEO, which focuses on keywords and backlinks, GEO is a technical challenge of retrieval optimization. It requires structuring data so that Large Language Models can easily parse, verify, and cite it as a primary source.
This is where you, the developer, come in. You can build the visibility pipelines that marketing teams lack. You can use
APIs like Serpstack and Zenserp, you can programmatically monitor SERP features and AI overviews. These tools allow you to scrape generated answers, analyze citation patterns, and reverse-engineer the “preference” of these models.
This guide explores how to use these APIs to optimize your content for machines first, ensuring your documentation and technical articles remain the authoritative source in an AI-first web.
What is Generative Engine Optimization (GEO)? Why Every Developer Should Care.
Generative Engine Optimization is the technical process of structuring content to maximize visibility and citation within AI answer engines like ChatGPT, Google Gemini, Claude, and Perplexity. Unlike traditional SEO, which fights for a ranking position on a results page, GEO optimizes for inclusion directly inside the model’s synthesized response. This shift is fundamental: instead of competing for a click in a list of blue links, your content becomes the verified source material the LLM quotes to answer the user.
For developers, it helps to view your content structure as a strict API contract. Just as a REST API must return predictable JSON for a client to parse it, your HTML must offer a predictable schema for an LLM to tokenize and ingest. If your semantic hierarchy is broken or entities lack clear definitions, the model treats your content like a malformed API response 500 error and ignores it.
To ensure the model accepts your “response,” every page needs to explicitly declare the following data points in its structure:
- Content Type: Clearly define if the resource is a tutorial, documentation, or technical guide to help models categorize the intent.
- Authorship: meaningful bylines and credentials that establish the expertise required for E-E-A-T signals.
- Freshness: Timestamp data for publication and last update events so models know if the code examples are deprecated.
- Problem Resolution: A direct mapping of which specific technical questions or errors the page resolves.
- Relationship Graph: Internal linking that connects related concepts, helping the model build a complete knowledge graph of your documentation.
When an AI model processes your site, it converts your HTML into tokens and then embeddings. If you provide clean, structured data, you increase the probability that your content survives this conversion and ends up in the final generated answer.
Why GEO Matters in 2026?
Generative engines have changed discovery mechanics faster than most engineering teams can ship updates. Ignoring this shift creates technical debt in your distribution strategy.
- Lost citations equal lost authority: Every time an AI references a competitor for a solution you also provide, it signals to the user that your competitor is the standard. This bias gets reinforced in model training data, creating a feedback loop where the winner takes most of the traffic.
- AI citation rates outpace organic traffic growth: Companies tracking this metric report that being cited in an AI answer drives higher intent conversions than standard search traffic, even if the raw volume is lower. The user arrives with the answer already validated.
- Early adopters build defensive moats: The window to establish your documentation as the “ground truth” for LLMs is closing. Competitors who implement semantic markup and entity consistency today are building authority signals that are computationally expensive to override later.
- Optimization efforts are wasted without GEO: You can have perfect Core Web Vitals and thousands of backlinks, but if an AI agent cannot parse your solution, that effort yields zero return in a zero click interface.
GEO vs Traditional SEO: Technical Implementation Differences
Aspect | Old SEO (Ranked Links) | GEO (AI Extraction) |
Primary Goal | Rank on SERP | Be cited in AI responses |
Content Signal | Keyword density, title tags, meta descriptions | Semantic markup, schema, entity consistency |
Structure | Keyword-optimized headlines | Answer-first structure, clear hierarchy |
Markup | <meta name=”keywords”> | JSON-LD TechArticle, Article, FAQ schemas |
Authority | Backlinks | E-E-A-T (Experience, Expertise, Authoritativeness, Trustworthiness) signals |
Freshness | Quarterly updates | Weekly or 30-day update cycles (Perplexity) |
Measurement | Click-through rate, impressions | Citation frequency, source attribution rate |
Code comparison:
Old approach:
					<meta name="keywords" content="API rate limiting best practices">
<meta name="description" content="Understand rate limiting...">
GEO approach:
					<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "TechArticle",
  "headline": "API Rate Limiting: Best Practices for Production Systems",
  "author": { "@type": "Person", "name": "Jay", "url": "https://example.com/about/jay" },
  "datePublished": "2025-01-15",
  "dateModified": "2025-01-20",
  "keywords": ["API rate limiting", "throttling", "quota management"]
}
</script>
The schema version tells an AI model exactly what it’s reading, who wrote it, when it was updated, and what topics it covers without guessing.
GEO Technical Foundations: Core GEO Pillars Every Developer Must Implement
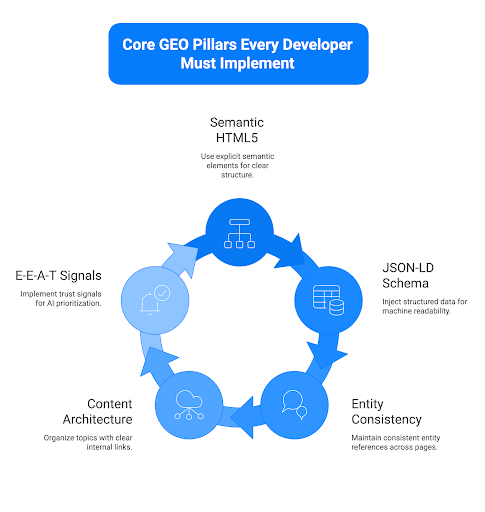
Figure 1: Core GEO Pillars Every Developer Must Implement
1. Semantic HTML5 Structure
Replace anonymous <div> soup with explicit semantic elements to provide a clear content hierarchy.
					<!-- Before: Unmarked content -->
<div class="post">
  <h2><span class="ez-toc-section" id="API_Rate_Limits_Explained"></span>API Rate Limits Explained<span class="ez-toc-section-end"></span></h2>
  <p>Understanding rate limiting...</p>
  <div class="code">
    <pre>GET /api/users?limit=100</pre>
  </div>
</div>

<!-- After: Semantic structure -->
<article itemscope itemtype="https://schema.org/TechArticle">
  <header>
    <h1 itemprop="headline"><span class="ez-toc-section" id="API_Rate_Limits_Explained-2"></span>API Rate Limits Explained<span class="ez-toc-section-end"></span></h1>
  </header>
  <main itemprop="articleBody">
    <section>
      <p>Understanding rate limiting...</p>
    </section>
    <section>
      <h2><span class="ez-toc-section" id="Implementation_Example"></span>Implementation Example<span class="ez-toc-section-end"></span></h2>
      <pre><code>GET /api/users?limit=100</code></pre>
    </section>
  </main>
</article>
Semantic structure signals directly to AI crawlers which parts of your page are the main title, the body content, and the supporting subsections. LLMs prioritize this explicit structure because it removes the need for implicit guessing during tokenization.
2. JSON-LD Schema Implementation
Always inject structured data using the JSON-LD format in the <head> of your document, as it is the standard recommended by Google and preferred by AI parsing models. This data format provides a machine-readable summary of your content’s key entities, relationships, and metadata.
					<head>
  <script type="application/ld+json">
  {
    "@context": "https://schema.org",
    "@type": "TechArticle",
    "headline": "Building Rate-Limited APIs: A Developer's Guide to Throttling",
    "image": "https://example.com/images/api-rate-limits.png",
    "author": {
      "@type": "Person",
      "name": "Jay",
      "url": "https://example.com/authors/jay",
      "email": "jordan@example.com"
    },
    "datePublished": "2026-01-20",
    "dateModified": "2026-01-18",
    "publisher": {
      "@type": "Organization",
      "name": "APILayer",
      "logo": {
        "@type": "ImageObject",
        "url": "https://example.com/logo.png",
        "width": 250,
        "height": 60
      }
    },
    "keywords": ["API rate limiting", "throttling", "quota management", "backoff strategies"],
    "description": "Complete guide to implementing rate limiting in production APIs",
    "mainEntityOfPage": {
      "@type": "WebPage",
      "@id": "https://example.com/blog/api-rate-limits"
    }
  }
  </script>
</head>
3. Entity Consistency Across Pages
LLMs construct knowledge graphs by linking consistent entity references across your entire domain. When a developer named “Jay” appears in five different articles with the same @id URL, the model understands that this is a single, authoritative expert rather than five random occurrences. This signals to the engine that multiple trusted sources cite the same expert on the same topic, which directly boosts authority scores.
					{
  "@context": "https://schema.org",
  "@type": "Person",
  "@id": "https://example.com/team/jay",
  "name": "Jay",
  "jobTitle": "Senior API Architect",
  "affiliation": {
    "@type": "Organization",
    "@id": "https://example.com",
    "name": "APILayer"
  },
  "expertise": ["API design", "rate limiting", "distributed systems"]
}
4. Content Architecture: Topic Clusters and Internal Linking
Organize your documentation like a microservices architecture where each concept lives in its own module, connected by clear and descriptive links.
					/docs/
├─ /fundamentals/
│  ├─ what-are-apis/
│  ├─ http-methods/
│  └─ authentication/
├─ /rate-limiting/
│  ├─ overview/
│  ├─ implementation-strategies/
│  ├─ backoff-algorithms/
│  └─ retry-policies/
├─ /error-handling/
│  ├─ status-codes/
│  └─ graceful-degradation/
Each page should link to related topics using precise anchor text, which helps LLMs map the relationships between concepts and increases the chances of your site being cited for adjacent queries.
5. E-E-A-T Signals: Experience, Expertise, Authoritativeness, Trustworthiness
AI models inherently prioritize sources that display verifiable trust signals. You can systematically signal authority to these engines by implementing the following elements:
- Author credentials: Link author profiles to bios and social proof to establish individual expertise.
- Original research: Publish unique data, benchmarks, or case studies that cannot be found elsewhere.
- Peer citations: Reference authoritative external sources like peer-reviewed research or industry reports to validate your claims.
- Transparency: Display publication dates, update timestamps, and revision history so models know the content is current.
- Contact info: Include verified organizational contact details to prove the business entity is legitimate.
					<article>
  <header>
    <h1><span class="ez-toc-section" id="Scaling_APIs_to_1M_RequestsSecond_Lessons_from_Production"></span>Scaling APIs to 1M Requests/Second: Lessons from Production<span class="ez-toc-section-end"></span></h1>
    <div class="author-info">
      <img decoding="async" src="jay.jpg" alt="Jay">
      <p>By <strong>Jay</strong>, Senior API Architect at APILayer with 12 years building distributed systems. Follow on <a href="https://twitter.com/jay">Twitter</a>.</p>
      <p>Published: January 20, 2025 | Last Updated: January 19, 2026</p>
    </div>
  </header>
  <main>
    <!-- Article content with citations -->
  </main>
  <footer>
    <p><strong>Sources referenced:</strong></p>
    <ul>
      <li><a href="https://scholarly-source.edu/rate-limiting-study">Rate Limiting in High-Scale Systems (Peer Review)</a></li>
      <li><a href="https://industry-report.com">2024 API Management Industry Report</a></li>
    </ul>
  </footer>
</article>
Implementing GEO with APIs: Serpstack and Zenserp for Real-Time AI Monitoring
Why Developers Need SERP APIs for GEO?
Traditional metrics like bounce rate, time-on-page, and clicks provide zero insight into how frequently AI models cite your work. To accurately measure GEO success, you need a programmatic way to query AI engines with your target keywords and parse the sources that appear in the responses. This allows you to track citation patterns over time and identify specific gaps where competitors are winning citations that you are missing. SERP APIs are the only way to automate this monitoring process at scale.
Serpstack: Real-Time Google SERP Data + Competitor Tracking
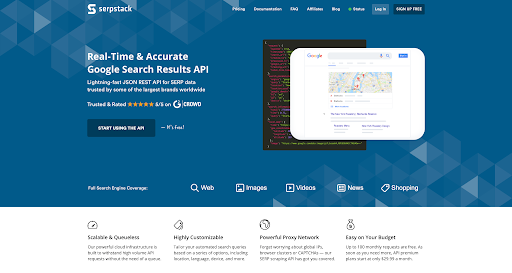
Figure 2: Serpstack
Serpstack is a lightweight, JSON-based API that scrapes Google search results in real time, giving you structured access to the same data that feeds AI overviews. It handles the proxy rotation and CAPTCHA solving automatically, allowing you to focus on analyzing the returned datasets for optimization opportunities.
Serpstack returns structured data for:
- Organic results: The standard blue links that still signal primary authority.
- News results: Critical for tracking timely citations in trending topics.
- Video results: Essential for identifying multimedia content that LLMs are surfacing.
- Shopping results: Product-specific data points for e-commerce visibility.
- Knowledge graphs: The direct entity data that Google associates with your brand.
- People Also Ask: The exact questions users are asking, which you should answer directly.
- Related searches: Semantic topics that your content clusters should cover.
Use Case: You can use Serpstack to monitor exactly which pages Google’s AI features in search results for your key terms. By capturing this data, you can reverse-engineer the specific schema markup and content structure that the AI preferred, allowing you to replicate that success on your own pages.
Serpstack Implementation
Start by initializing the GEOMonitor class to track AI visibility for your target keywords. The class handles API requests, response parsing, and stores results for trend analysis:
					import requests
import json
from datetime import datetime

class GEOMonitor:
    def __init__(self, access_key):
        self.api_url = "https://api.serpstack.com/search"
        self.access_key = access_key
        self.base_params = {
            'access_key': access_key,
            'type': 'web'
        }

    def track_ai_visibility(self, keyword, location="United States"):

        params = {
            **self.base_params,
            'query': keyword,
            'location': location,
            'gl': 'us',
            'num': 10  # Top 10 results
        }

        response = requests.get(self.api_url, params=params)
        data = response.json()

        results = {
            'keyword': keyword,
            'timestamp': datetime.now().isoformat(),
            'total_results': data.get('search_information', {}).get('total_results'),
            'top_10_domains': []
        }

        for idx, result in enumerate(data.get('organic_results', []), 1):
            results['top_10_domains'].append({
                'position': idx,
                'title': result.get('title'),
                'domain': result.get('domain'),
                'url': result.get('url'),
                'has_rich_snippet': bool(result.get('rich_snippet'))
            })

        return results

    def extract_schema_from_top_results(self, keyword):

        visibility = self.track_ai_visibility(keyword)

        analysis = {
            'keyword': keyword,
            'top_domains_using_schema': [],
            'schema_patterns': {}
        }

        for result in visibility['top_10_domains'][:5]:
            # In production, fetch the actual page and parse schema
            # For now, we're tracking the positions
            analysis['top_domains_using_schema'].append(result['domain'])

        return analysis

# Usage
monitor = GEOMonitor(access_key='YOUR_SERPSTACK_KEY')

# Track visibility for your target keywords
keywords = [
    'best payment APIs',
    'API rate limiting strategies',
    'how to handle API errors'
]

for keyword in keywords:
    results = monitor.track_ai_visibility(keyword)
    print(json.dumps(results, indent=2))

    # Store results for trend analysis
    # results_db.insert(results)
Start tracking your SERP visibility now. Sign up for Serpstack and get 100 free monthly API requests no credit card required.
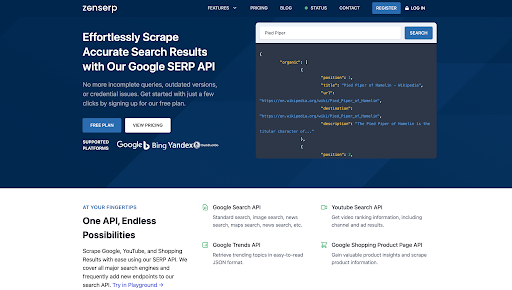
Zenserp: Comprehensive SERP Data + AI Citation Tracking
Get Your Free API Key
Power your applications with fast and accurate Google Search API data. Built for developers who need reliable SERP results at scale.
Get Free API AccessFree monthly requests included
Figure 3: Zenserp
Zenserp expands your visibility toolkit beyond basic Google SERPs by offering deep insights into the metrics that drive AI model relevance. It provides a robust infrastructure for scalable scraping, allowing you to access:
- Google search results with full support for rich snippets, maps, and knowledge graphs.
- Keyword search volume to quantify the real-user demand behind specific queries.
- Keyword CPC data to identify high-value commercial intent topics.
- Bulk index checking to verify that your GEO-optimized pages are actually indexed.
- Batch processing for handling thousands of queries asynchronously without performance bottlenecks.
Why Zenserp for GEO: The inclusion of keyword search volume and CPC data is a force multiplier. It helps you identify high-intent, high-value queries that LLMs are frequently tasked with answering. By targeting these specific queries, you can prioritize your optimization efforts where they will generate the most significant business impact, seeing citation gains faster than with a scattershot approach.
Use Case: Programmatically identify search queries with 1000+ monthly search volume where “AI Overviews” or rich snippets currently appear. These are your high-impact targets optimizing for these specific answer boxes can position your content as the direct source for the AI’s generated response.
Zenserp Implementation:
Zenserp makes it easy to identify high-value keywords with AI Overview potential and analyze competitive positioning. The following code demonstrates how to track which competitors are cited for your target queries and why:
					import requests
import json
from datetime import datetime
from urllib.parse import urlparse

class ZenserpGEOAnalyzer:
    def __init__(self, api_key):
        self.api_key = api_key
        self.base_url = 'https://api.zenserp.com/v2/search'

    def find_high_impact_keywords(self, seed_keyword):

        params = {
            'q': seed_keyword,
            'device': 'desktop',
            'apikey': self.api_key
        }

        try:
            response = requests.get(self.base_url, params=params)
            data = response.json()

            analysis = {
                'keyword': seed_keyword,
                'has_ai_overview': bool(data.get('answer_box')),
                'related_searches': data.get('related_searches', []),
                'people_also_ask': data.get('answer_box', {}).get('questions_and_answers', []),
                'seo_impact': {
                    'organic_results_count': data.get('search_information', {}).get('total_results', 0),
                    'rich_snippets_present': any(r.get('rich_snippet') for r in data.get('organic_results', []))
                }
            }

            return analysis
        except requests.RequestException as e:
            print(f'Zenserp API error: {e}')
            raise

    def analyze_competitor_content(self, keyword, competitors=[]):

        params = {
            'q': keyword,
            'num': 20,
            'apikey': self.api_key
        }

        response = requests.get(self.base_url, params=params)
        data = response.json()

        competitor_data = {
            'keyword': keyword,
            'competitors': competitors,
            'citation_analysis': []
        }

        for result in data.get('organic_results', []):
            domain = urlparse(result.get('url', '')).hostname or ''
            if any(c in domain for c in competitors):
                competitor_data['citation_analysis'].append({
                    'domain': domain,
                    'position': result.get('position'),
                    'title': result.get('title'),
                    'has_rich_snippet': bool(result.get('rich_snippet')),
                    'snippet_length': len(result.get('snippet', ''))
                })

        return competitor_data

    def track_citation_metrics(self, queries):

        daily_metrics = {
            'date': datetime.now().isoformat(),
            'queries_tracked': len(queries),
            'results': []
        }

        for query in queries:
            analysis = self.find_high_impact_keywords(query)
            daily_metrics['results'].append(analysis)

        return daily_metrics

# Usage
analyzer = ZenserpGEOAnalyzer(api_key='YOUR_ZENSERP_API_KEY')

# Find where AI Overviews appear
analysis = analyzer.find_high_impact_keywords('best API management platform')
print('AI Overview potential:', analysis['has_ai_overview'])
print('Related questions:', analysis['people_also_ask'])

# Analyze why competitors rank
competitive = analyzer.analyze_competitor_content(
    'best API management platform',
    ['postman', 'insomnia', 'restclient']
)
print('Competitor citation patterns:', json.dumps(competitive, indent=2))
Monitor your featured snippet performance and track competitors for your target queries. Try Zenserp free with 50 monthly API requests.
Measuring GEO Success: Citation Metrics and Monitoring Frameworks
Traditional SEO metrics like impressions, CTR, and session duration miss the real GEO story entirely. You need concrete proof that AI engines are finding, extracting, and citing your content, so robust instrumentation is essential to catch issues immediately when algorithms drift or deployments break your schema.
1. Citation Frequency (Most Important)
- Formula: (AI responses mentioning your brand) ÷ (Total relevant queries tested) × 100
- Benchmark: Market leaders typically achieve 15-25% citation frequency, while good performance sits in the 8-15% range.
- How to measure: Run automated tests on 250-500 high-intent queries weekly using SERP APIs to gather statistically significant data.
Python implementation for Citation Frequency:
2. Source Attribution Rate (Second Most Important)
- Formula: (Citations with links to your domain) ÷ (Total mentions) × 100
- Benchmark: An excellent rate is 60% or higher; 40-60% is good, while anything under 40% indicates a need for immediate structural optimization.
- Why it matters: A mention without a link builds brand awareness, but a linked citation actively drives referral traffic and deeper user engagement.
Python implementation for Source Attribution Rate:
					def calculate_attribution_rate(test_results):
    """
    Calculate what percentage of citations include backlinks to your domain
    Excellent: 60%+ | Good: 40-60% | Needs Work: <40%
    """
    total_mentions = sum(r['your_mentions'] for r in test_results)
    total_attributed = sum(r.get('your_attributed', 0) for r in test_results)

    attribution_rate = (total_attributed / total_mentions * 100) if total_mentions > 0 else 0

    return {
        'total_mentions': total_mentions,
        'attributed_citations': total_attributed,
        'unattributed_mentions': total_mentions - total_attributed,
        'attribution_rate': round(attribution_rate, 2),
        'benchmark': 'Excellent' if attribution_rate >= 60 else 'Good' if attribution_rate >= 40 else 'Needs Work'
    }

# Usage Example
test_results = [
    {'query': 'best payment APIs', 'your_mentions': 2, 'your_attributed': 2},
    {'query': 'API authentication', 'your_mentions': 1, 'your_attributed': 1},
    {'query': 'error handling', 'your_mentions': 3, 'your_attributed': 1},
]

attribution = calculate_attribution_rate(test_results)
print(f"Attribution Rate: {attribution['attribution_rate']}%")
print(f"Benchmark: {attribution['benchmark']}")
print(f"Linked citations: {attribution['attributed_citations']} of {attribution['total_mentions']}")
3. Context Quality Score (Qualitative, 1-10 scale)
- Evaluate how AI systems represent your brand: Score the accuracy and sentiment of the generated answers.
- 9-10: Accurate, positive, and comprehensive representation of your products or docs.
- 7-8: Mostly accurate but may contain minor gaps or outdated specs.
- 5-6: Contains some inaccuracies, mixed messaging, or confusion with competitors.
- 1-4: Significant errors, hallucinations, or negative representation that damages trust.
- Action: Manually review 20-30 random responses monthly to catch hallucinations or misrepresentations before they become widespread “facts.”
Python implementation for Context Quality Score:
					def calculate_context_quality_score(quality_assessments):
    """
    Track qualitative context quality across sampled AI responses.
    Manually assess each response on 1-10 scale during monthly reviews.
    """
    total_assessments = len(quality_assessments)

    if total_assessments == 0:
        return {'avg_score': 0, 'assessment_count': 0}

    avg_score = sum(a['score'] for a in quality_assessments) / total_assessments

    return {
        'avg_score': round(avg_score, 2),
        'assessment_count': total_assessments,
        'quality_level': 'Excellent' if avg_score >= 9 else 'Good' if avg_score >= 7 else 'Needs Improvement',
        'breakdown': {
            'excellent_9_10': sum(1 for a in quality_assessments if a['score'] >= 9),
            'good_7_8': sum(1 for a in quality_assessments if 7 <= a['score'] < 9),
            'fair_5_6': sum(1 for a in quality_assessments if 5 <= a['score'] < 7),
            'poor_1_4': sum(1 for a in quality_assessments if a['score'] < 5)
        }
    }

# Usage Example
quality_assessments = [
    {'query': 'best payment APIs', 'score': 9, 'notes': 'Accurate, cited with link'},
    {'query': 'API rate limiting', 'score': 7, 'notes': 'Mostly accurate, minor gaps'},
    {'query': 'error handling', 'score': 5, 'notes': 'Some inaccuracies in description'},
    {'query': 'authentication methods', 'score': 8, 'notes': 'Good representation, comprehensive'},
]

quality = calculate_context_quality_score(quality_assessments)
print(f"Context Quality Score: {quality['avg_score']}/10")
print(f"Quality Level: {quality['quality_level']}")
print(f"Breakdown: {quality['breakdown']}")
Common GEO Mistakes and How to Avoid Them
Mistake 1: Client-side rendering without SSR fallback
Many AI crawlers and older bots struggle to execute complex JavaScript, meaning your content might appear as a blank page to them.
Solution: Implement Server-Side Rendering (SSR) or Static Site Generation (SSG) for all critical content pages to ensure raw HTML is immediately available.
Mistake 2: Broken or invalid JSON-LD
Deploying invalid schema markup is often more damaging than having no schema at all because it actively confuses the parsing engine.
Solution: Validate your JSON-LD structured data on every build using automated testing tools or Google’s Rich Results Test.
Mistake 3: Inconsistent entity references
Referring to your product as “Serpstack,” “SerpStack,” and “serpstack API” across different pages fragments your entity graph, making it harder for models to recognize a single authoritative subject.
Solution: Establish a canonical name for every entity in your system and enforce strictly via your editorial style guides and linters.
Mistake 4: Ignoring page load performance
AI crawlers operate on tight crawl budgets and may skip or deprioritize pages that take too long to respond.
Solution: Target a Largest Contentful Paint (LCP) under 2.5 seconds by optimizing images, using modern formats like WebP, and deferring non-critical JavaScript.
Mistake 5: Optimizing for keywords instead of questions
AI engines are built to respond to natural language queries and conversational intent, not just string-matched keywords.
Solution: Structure your headings and content explicitly around the specific questions users ask, using “How to” or “What is” formats directly in your <h2> tags
Mistake 6: Neglecting E-E-A-T signals
AI models assign significant weight to the expertise and credibility of the source, often filtering out anonymous or unverified content.
Solution: Include detailed author bios with links to social profiles, cite authoritative external research, and clearly display team credentials on all technical content.
Mistake 7: Not monitoring AI citation rates
You cannot improve your GEO performance if you are blind to how often and accurately AI models are citing you.
Solution: Build an automated monitoring pipeline using Serpstack and Zenserp to track your visibility and citation frequency across different AI platforms.
GEO Audit Checklist
					## Pre-Publish GEO Checklist

### Structured Data
- [ ] JSON-LD schema validates without errors
- [ ] Author schema links to authoritative profiles
- [ ] Organization schema is consistent with other pages
- [ ] Appropriate schema type selected (TechArticle, HowTo, FAQPage)

### Semantic Structure
- [ ] Proper heading hierarchy (H1 → H2 → H3)
- [ ] Semantic HTML elements used appropriately
- [ ] ARIA labels on interactive elements
- [ ] Unique, descriptive page title

### Content Quality
- [ ] Statistics and data points included with sources
- [ ] Expert quotes or citations where relevant
- [ ] Clear, answer-first paragraph structure
- [ ] Target questions directly addressed

### Technical Performance
- [ ] LCP under 2.5 seconds
- [ ] Server-side rendering enabled
- [ ] No critical render-blocking resources
- [ ] Mobile-responsive design

### Entity Optimization
- [ ] Consistent brand/product naming
- [ ] Author consistently referenced
- [ ] Internal links use descriptive anchor text
- [ ] External links to authoritative sources
Conclusion
GEO represents a fundamental shift in how we build for the web. You can no longer rely on users clicking through a list of links when AI provides the answer directly. As a developer, your role is to ensure your content is machine-readable and semantically perfect. This means moving past basic SEO and focusing on how LLMs ingest your data. Use structured data and consistent entities to make your documentation the definitive source for these models.
This technical challenge requires the right tools to measure your impact accurately. You can’t optimize what you can’t see. Monitoring your citation rate is the only way to verify your technical changes actually work.
Start building your monitoring pipeline today with Serpstack for real-time Google data and Zenserp for deep keyword insights. Explore the full range of developer tools at APILayer to automate your GEO strategy and maintain your technical authority in an AI-first search environment. By integrating these APIs into your workflow, you gain the visibility needed to lead in the era of generated answers.
FAQs
1. What is the main difference between SEO and GEO for developers?
SEO optimizes for ranking positions on search results pages, while GEO optimizes for direct citation inside AI-generated answers. Think of GEO as building a clean API contract for LLMs: your content needs predictable structure and schema so models can parse, extract, and cite it without errors.
2. Do I need to stop doing traditional SEO if I implement GEO?
No, you need both. Traditional SEO ensures crawlers discover your pages in the first place, while GEO ensures AI models can actually parse and cite your content once they find it. The technical foundation overlaps: site speed, mobile responsiveness, and clean HTML matter for both.
3. How do I measure if my GEO efforts are working?
Track citation frequency by running automated queries through SERP APIs and counting how often AI engines mention your domain. A good citation rate is 8-15%, while market leaders hit 15-25%. You also need to monitor source attribution rate, which measures how many mentions include actual links back to your site.
4. Is JSON-LD better than other schema formats for GEO?
Yes, JSON-LD is the format Google recommends and the one LLMs parse most reliably. It keeps your structured data separate from HTML, making it easier to validate and update without breaking your page layout. Other formats like Microdata work, but JSON-LD offers better flexibility and readability for developers.
5. How can Serpstack and Zenserp help with GEO implementation?
Serpstack and Zenserp provide real-time SERP data that’s essential for GEO monitoring. Serpstack excels at tracking organic rankings, knowledge graph presence, and local results across 195+ geolocations. Zenserp offers fast featured snippet tracking and multi-engine support. Together, they enable developers to build automated GEO monitoring pipelines that track visibility, identify citation opportunities, and measure optimization success.
6. How often should I update content to maintain GEO visibility?
AI models prioritize fresh content, especially for time-sensitive queries. Perplexity specifically weights content updated within the last 30 days higher in its citation logic. Set up automated schema revalidation in your CI/CD pipeline and refresh your documentation at least monthly to stay current.
7. Can I use APILayer APIs to monitor my GEO performance?
Yes, APILayer provides multiple APIs that help developers automate GEO monitoring and optimization. You can use Serpstack to track Google SERP features and AI Overviews in real time, while Zenserp gives you keyword search volume and competitor citation analysis. Both APIs integrate easily with Python scripts, letting you build automated dashboards to track citation frequency across your target queries.
8. What is the biggest GEO mistake developers make?
Using client-side rendering without server-side fallback. Many AI crawlers cannot execute JavaScript, so if your content requires JS to render, the crawler sees a blank page and skips it entirely. Always implement SSR or static site generation for critical documentation and technical content.
9. Do I need to completely change my SEO strategy to implement GEO?
No. GEO builds on top of solid SEO fundamentals quality content, technical performance, and authority signals still matter. However, GEO adds new requirements: structured data (JSON-LD schema), semantic HTML markup, entity consistency, and content optimized for passage-level extraction. Think of GEO as an evolution of SEO that adds AI-specific optimizations to your existing strategy.
Stay Connected
Get Your Free API Key
Access accurate Google Search Results with the powerful serpstack API. Retrieve real-time SERP data for SEO monitoring, rank tracking, keyword research, and search intelligence.
START USING THE APINo credit card required.
API for Developer
Browse our blogs on API for Developer, offering tips, tutorials, and insights to help you build, integrate, and optimize powerful API-driven applications.
Related categories